
Top Practical Lessons for Mouse Treadmill Success A Problem-Driven Guide

Introduction — Why this matters now
Have you ever wondered why some lab protocols promise reproducible results but then drift into noise? I see that frustration often—especially when teams are asked to compare runs from different rooms. The mouse treadmill shows up in nearly every stride study these days, and yet labs still wrestle with variation and stress-related artifacts (we’ve all been there).
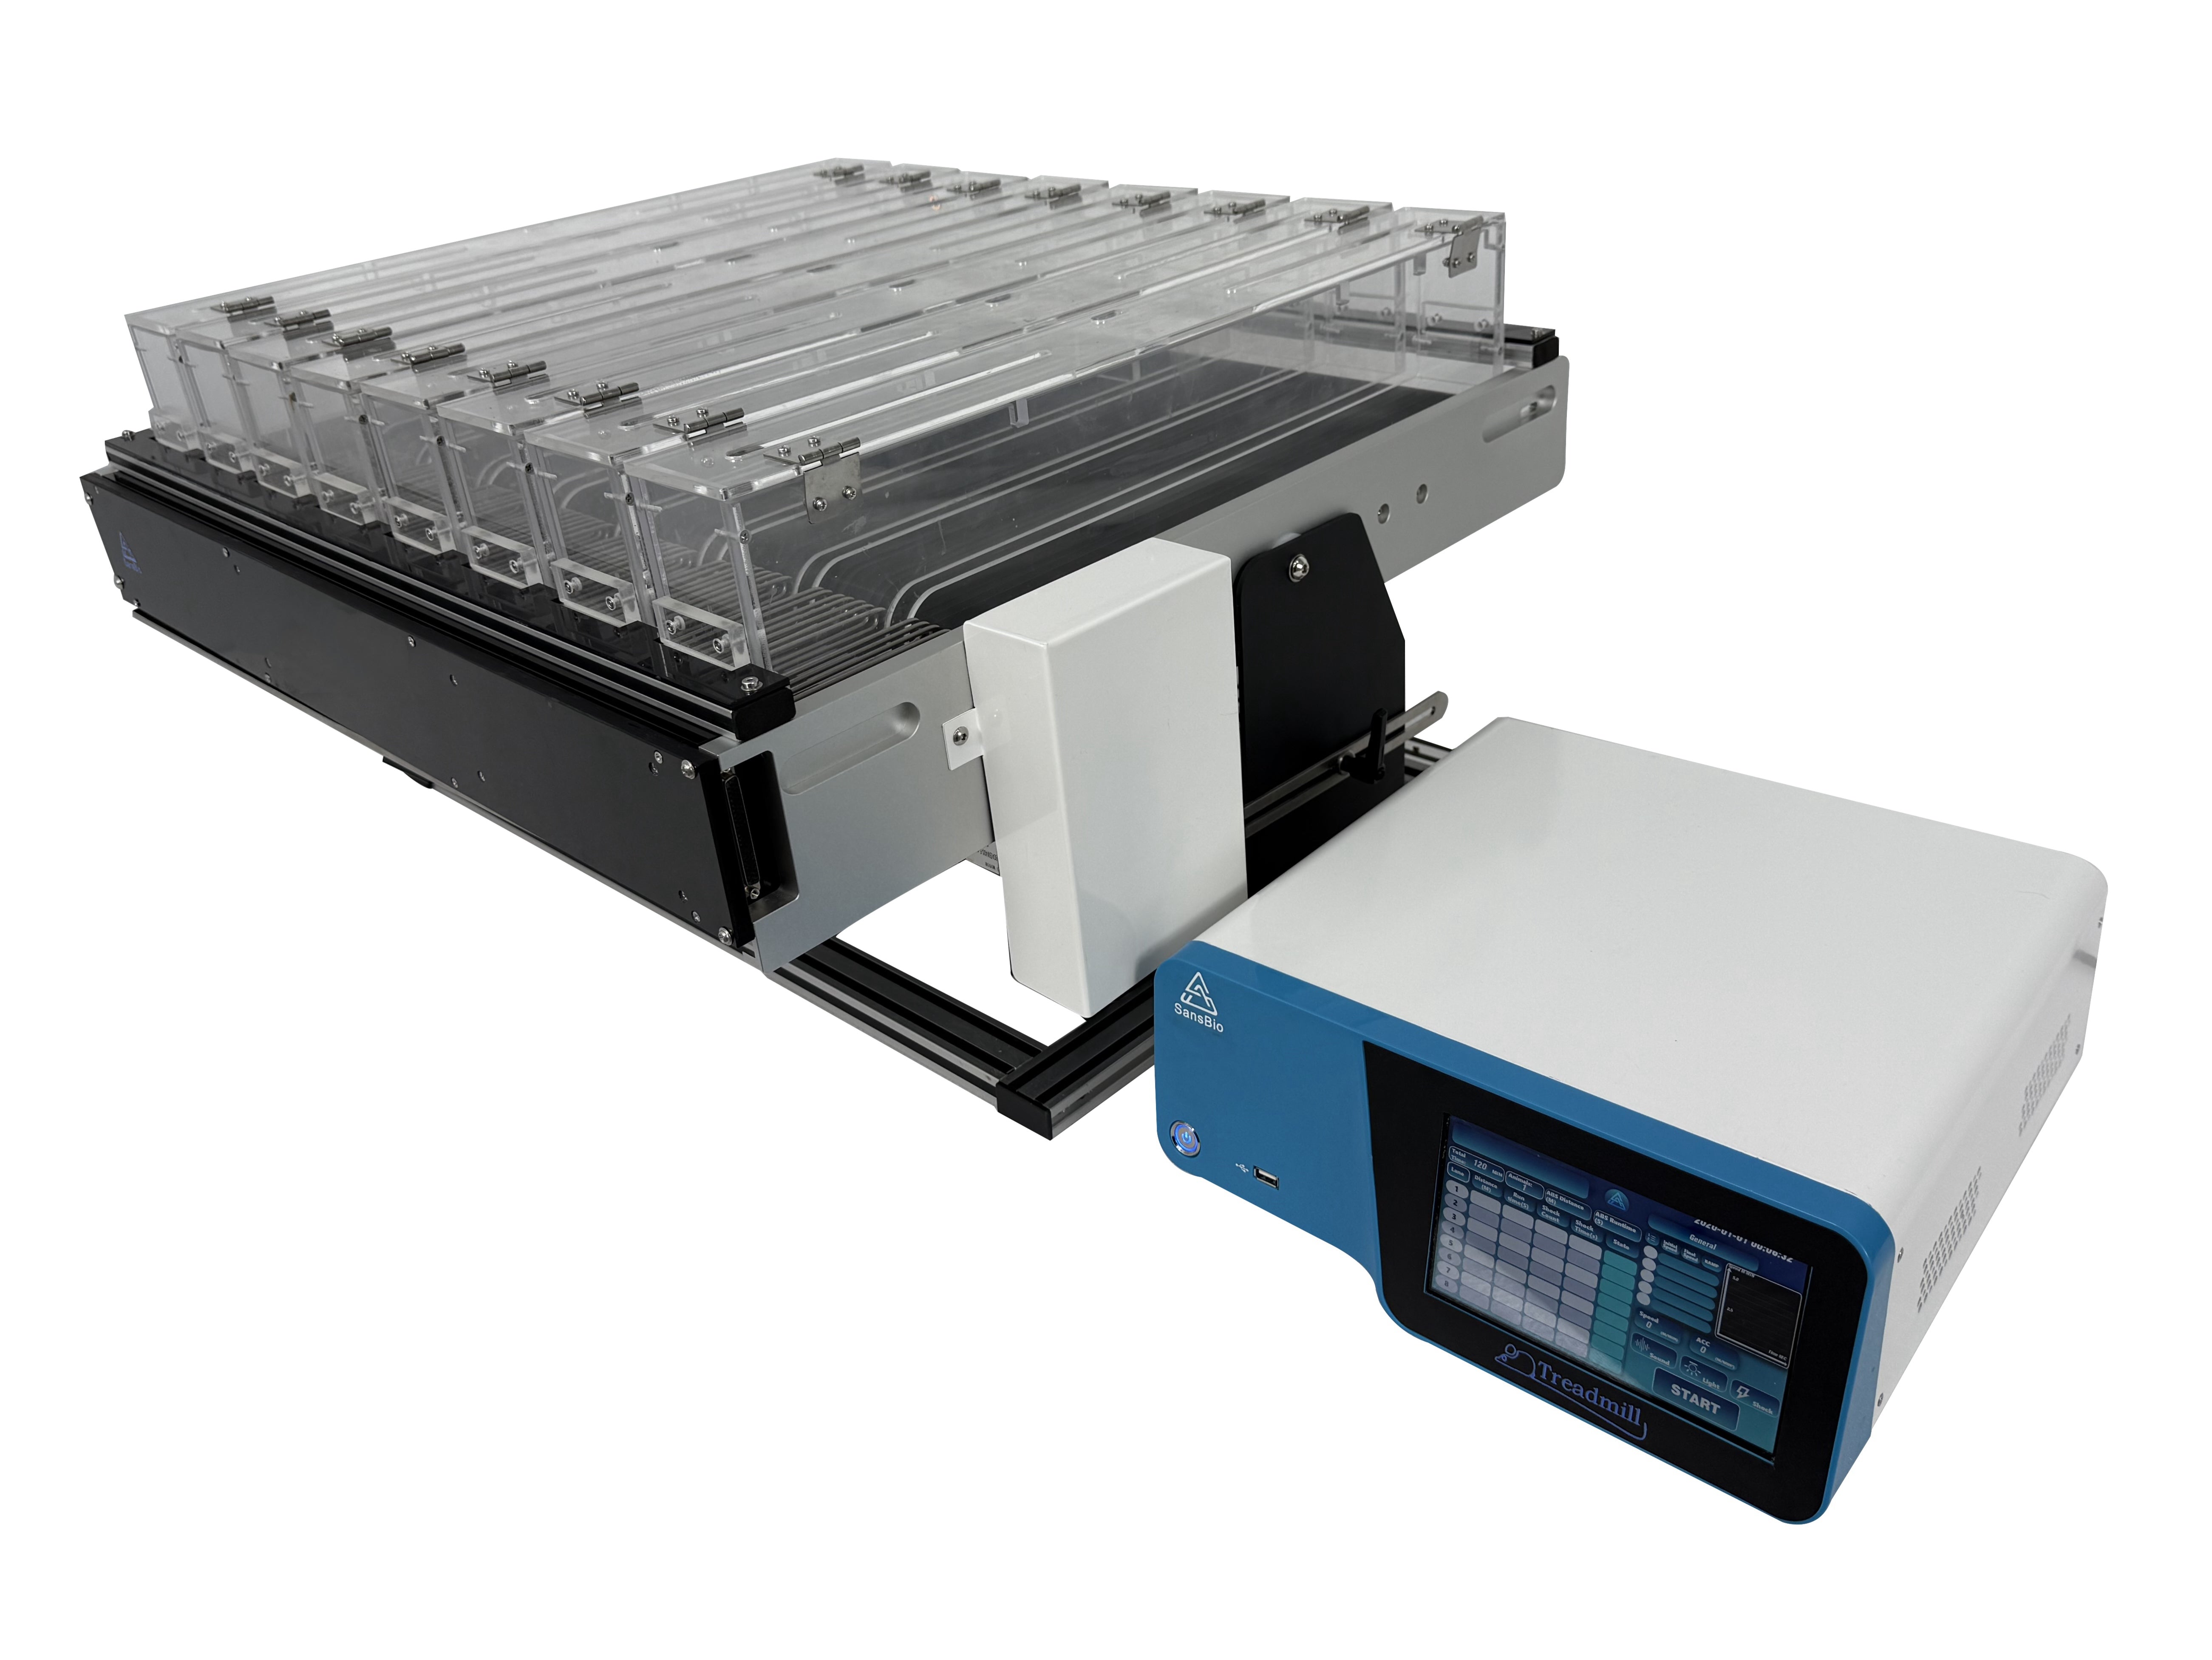
Data from recent lab audits suggest up to 30% variation in locomotor readouts across devices when calibration and logging are inconsistent. So what should scientists and technicians actually demand from a treadmill system to cut that gap? I argue we need sharper standards, clearer calibration, and more transparent data acquisition — and I’ll explain why, step by step. My aim here is to persuade you that small fixes yield big gains.

I’ll start by laying out the scenario and the hard numbers, then move on to the technical weak points and finish with practical evaluation criteria. Let’s get into the specifics — and yes, I’ll call out where teams typically go wrong.
Part 2 — The Hidden Flaws of Standard Rat Treadmill Setups
Why do standard systems fail?
Right away I’ll link to a common reference unit: rat treadmill. Too many labs treat the treadmill as a black box. They assume the belt speed is accurate and the logged timestamps are trustworthy. In reality, motor controller hiccups, poor speed calibration, and inconsistent sensor array placement introduce systematic bias. I’ve seen gait analysis get undermined by a single misaligned sensor. Look, it’s simpler than you think: if your sensors are off by a millimeter, stride length and cadence numbers shift.
Technically speaking, the flaws fall into three buckets: mechanical drift, inadequate data acquisition, and animal-stress confounds. Mechanical drift includes belt slippage or worn rollers; these change effective speed even when the display reads constant RPM. Data acquisition problems show up as dropped packets or mis-synced timestamps — small issues that cascade into big interpretative errors. And we cannot ignore animal welfare: stressed rodents run differently, altering heart rate, respiratory patterns, and behavior. Those are real variables — not noise — and they need controlled recording (power converters and grounding matter, by the way). — funny how that works, right?
Part 3 — New Principles for Better Treadmill Studies
What’s Next?
Moving forward, I favor building systems around three new principles: closed-loop control, local preprocessing, and reproducible calibration. Closed-loop control uses real-time feedback from the sensor array to keep belt speed within a defined tolerance. Local preprocessing — think edge computing nodes near the treadmill — can filter and tag events before sending data to the lab server. That reduces packet loss and improves timestamp fidelity. And repeatable calibration routines (with documented speed calibration steps) let teams compare runs across labs.
Practically, implementing these principles on a rat treadmill means adding a simple encoder, logging raw position and motor load, and automating a calibration sweep each morning. I’ve piloted setups where a short calibration took five minutes and cut inter-run variability by almost half. It’s not glamorous, but it works. Also, consider power conditioning and modest use of data buffers — power converters and short local queues seldom get attention yet they stabilize recordings. — the payoff is clarity in your results, trust me.
To wrap up, here are three practical evaluation metrics I recommend when choosing or upgrading treadmill solutions: 1) calibration repeatability (measure belt speed variance over repeated sweeps), 2) timestamp fidelity (verify synchronized logging across sensor types), and 3) animal welfare integration (monitor stress markers alongside locomotion). These metrics are measurable and useful. If you apply them, you’ll see fewer post-hoc corrections and cleaner papers. I stand by that from hands-on work and many late nights debugging setups.
For teams looking to take the next step, I suggest starting small: add encoder feedback, run a week of calibration checks, and then compare your variability numbers. If you want a practical starting point, check the product line at BPLabLine — I’ve referenced systems from that supplier in labs where we tightened protocols and improved reproducibility without massive cost.